October 26, 2026
An AI Tool Isn't a Pentest. It's a Faster Scanner.
An AI Tool Isn't a Pentest. It's a Faster Scanner.
Omair Manzoor

Fiza Nadeem is an SEO content writer at ioSENTRIX with 2.5+ years of experience in content writing, copywriting, and SEO.
AI red teaming is an adversarial testing discipline that evaluates how an AI system behaves under deliberate misuse, manipulation, and attack, rather than whether its code and infrastructure contain known vulnerabilities.
AI red teaming is the practice of attacking an AI system's behavior — its inputs, its decisions, and the actions it is permitted to take — to produce evidence of how it fails, not an assurance that it will not.
That last clause is the part most descriptions leave out. A red team engagement produces findings. It does not produce a guarantee, and a report that reads like one should be treated as a marketing document.
An AI red team engagement typically covers four surfaces:
Generative AI systems introduce a non-deterministic attack surface that traditional security testing was never designed to evaluate.
A conventional application usually fails the same way twice, and when it does not — a race condition, a load-dependent fault — testers treat the irreproducibility as the bug to chase. In a sampling-based generative system, irreproducibility is the normal operating condition. The system may refuse a request, comply with a reworded version of it, and comply with the original on a later attempt. A hosted model's version and system prompt can also change beneath a fixed test. Testing that assumes reproducibility reports a pass that a second run would contradict.
Worth scoping precisely, because it is often overstated: plenty of machine learning is deterministic at inference. A fixed-weight classifier returns the same output for the same input. The property this post is about belongs to generative systems and to hosted models that move under you.
The surface is also wider. Adversaries target model weaknesses — prompt injection, data poisoning, model inversion, unauthorized model abuse — rather than static code defects alone. As organizations deploy AI into fraud detection, customer service, clinical decision support, and financial workflows, the consequence of a manipulated decision stops being a software bug and becomes a business outcome.
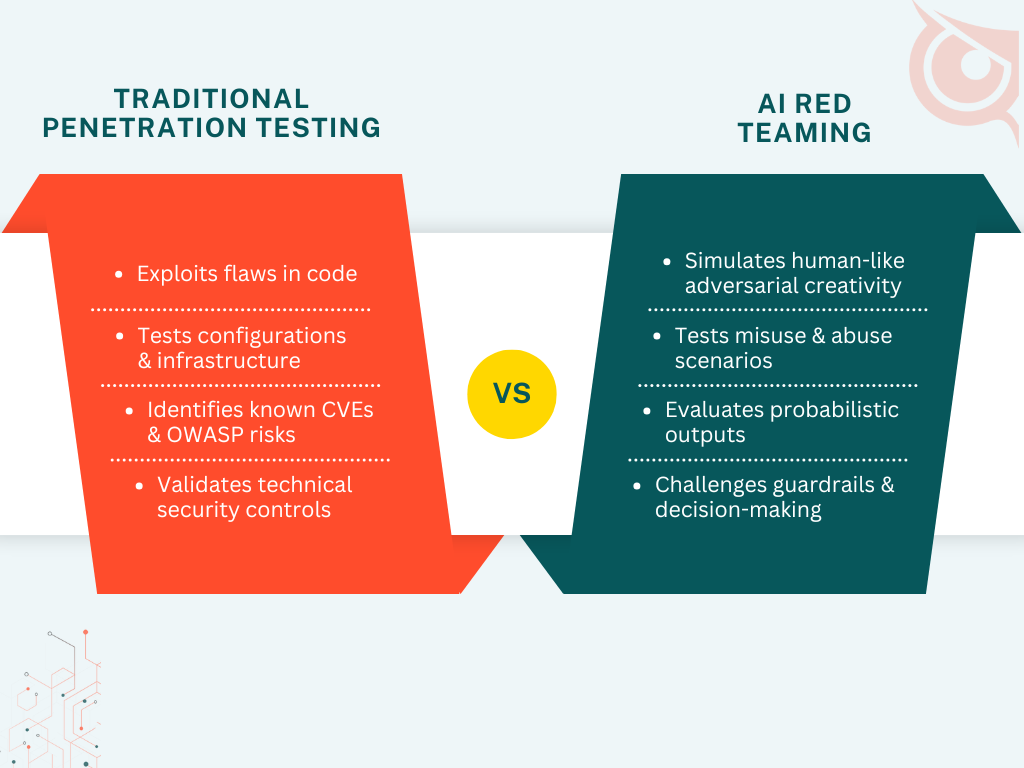
AI red teaming targets behavioral and logical weaknesses; traditional penetration testing targets technical ones. They are complements, not substitutes, and a mature program runs both.
Conventional testing identifies exploitable flaws in code, configuration, and infrastructure. AI red teaming asks a different question: given that the system works as built, what can it be persuaded to do?
If you are deciding how to split a budget between the two rather than how to run them, AI red teaming versus an AI security assessment covers that trade directly, and the scope of an AI penetration test sets out what belongs inside the engagement boundary.
AI red teaming surfaces threats a code-and-configuration test is not scoped to reach, because they exploit model behavior and data dependencies rather than defects in code. Some of the surface overlaps a conventional test — model hosting, APIs, integrations — and that overlap should be agreed in scope rather than tested twice or not at all.
The recurring ones:
AML.T0051 LLM Prompt Injection. OWASP's GenAI LLM Top 10 2026 ranks it first, as LLM01:2026. Our own walkthrough of how to test an LLM application for prompt injection sets out the method.LLM03:2026 in the OWASP list, up from sixth in the 2025 edition — an agent permitted to take an action it should have had to ask about. Testing this means attempting the action, not reading the permission policy. Penetration testing AI agents is where that gets concrete.
You measure an AI red team engagement by what it proved, not by what it found. The useful metrics are about coverage, reproducibility, and remediation, and most reports do not carry them.
Four that are worth asking a provider for before the engagement starts:
Attempted-versus-achieved, per objective. Not a finding count. A list of the adversary objectives in scope — exfiltrate the system prompt, cause an unauthorized tool call, poison a retrieval source — and for each, whether it was achieved, partially achieved, or defeated. A report with twenty low-severity findings and no objective outcomes has told you nothing about whether the system holds.
Reproduction rate. Because the system is non-deterministic, a successful attack should be stated as a rate across a stated number of attempts, not as a binary. A line of the form "succeeded 7 times in 40 attempts" is evidence. "Vulnerable to prompt injection" is a label.
Coverage against a named technique set, at a named version. Which MITRE ATLAS techniques were attempted and which were out of scope, stated explicitly, against a named ATLAS content release — ATLAS ships updates through the year, so "full ATLAS coverage" with no version attached is not a claim. Absence of a finding is only meaningful if the technique was tried.
Time to reproduce after remediation. The engagement is not finished when the report lands. Retesting a fix on a non-deterministic system is its own exercise, and a fix that holds for forty attempts and fails on the next one has not held.
The anti-metrics are as useful. A finding count, a severity distribution, and a percentage "secure" score tell you about the report, not the system. No number should be read as a statement that a control will hold; it is a statement that it held under the attempts that were made.
AI red teaming fails in predictable ways, and a provider who names them in advance is more credible than one who does not.
It is a point-in-time result on a moving target. Model versions change, system prompts get edited, retrieval corpora grow, and a provider updates a hosted model without telling you. A result from last quarter describes a system that may no longer exist. This is the same problem model drift creates for accuracy, applied to security.
Non-determinism cuts both ways. A technique that fails across fifty attempts may succeed at a higher attempt count. Red teaming can establish that an attack works. It cannot establish that one does not.
Scope boundaries hide risk. Most engagements test the model and its immediate interface. The failure that matters is often downstream, in whatever system consumed the output and acted on it. If the engagement stopped at the model boundary, the interesting half was out of scope.
Guardrail testing is often mistaken for system testing. A refusal is not a control. A model that declines a request in the chat interface may comply through a tool call, an API, or a different language. Testing the guardrail is a narrower exercise than testing the system around it.
Evidence is frequently not independent. If the only record of what the agent did is the log the agent wrote, the engagement has verified the system's own account of itself. Signal-layer assurance sets out why that record has to land somewhere the workload's own identity cannot modify.
AI red teaming maps onto several published frameworks and one binding law, and the difference between those two categories matters.
Four of these are voluntary frameworks. Mapping work to them demonstrates method, not compliance, and none turns a test result into a certification:
The EU AI Act is different in kind. It is binding law, and for a high-risk system the accuracy, robustness, and cybersecurity obligations in Article 15 feed a conformity assessment. Even there, a red team result is an input to that assessment, not a substitute for it. What Article 15 asks you to evidence is the practical read.
The pattern across all of them is the one that runs through compliant is not correct: a framework names the properties worth having. Only a test tells you whether you have them.
Run it before deployment and again whenever the system changes, because a one-time assessment of an adaptive system expires quietly.
Reasonable triggers:
The last one is worth separating from the others. Testing to produce evidence for a buyer is a different scope from testing to find problems, and conflating them produces a document that satisfies neither. What buyers should ask AI vendors is the other side of that conversation.
Threat modeling decides what the red team spends its time on, and without it an engagement defaults to the techniques the testers happen to know.
An AI-focused threat model examines the training and fine-tuning path, the data ingestion and preprocessing pipeline, the human-AI interaction points, the tools and identities the system can reach, and the downstream systems that act on its output. Threat modeling in application security covers the general method; the AI-specific addition is the identity question — which non-human identities the system holds and what each one can do.
You cannot threat model an inventory you do not have. Discovering the AI you already run usually comes first, and it usually finds more than expected.
Start by listing the AI systems you actually run, deciding which adversary objectives would matter most if achieved, and scoping an engagement against those objectives rather than against a technique checklist.
A practical first pass:
No. The trigger is what the system is permitted to do, not company size. An agent at a fifty-person company that can issue refunds or read a customer database warrants testing more than a large enterprise's internal summarization tool.
No. It complements it. Traditional penetration testing covers the infrastructure, APIs, and application layer the AI system runs on; AI red teaming covers model behavior and the decisions it drives. Dropping either leaves a gap.
After any material change to the model, data, tools, or permissions, and on a recurring schedule between changes. Continuous testing versus an annual audit covers why the cadence matters more for adaptive systems.
No. It reduces the likelihood of one by finding misuse paths that lead to data exposure, and it produces evidence about which paths stopped working under retest, with the attempt counts attached. No control eliminates breach risk, and a provider who implies otherwise is selling something.
The adversary objectives in scope, the outcome of each, reproduction rates with attempt counts, the technique coverage attempted and excluded at a named version, and the limitations of the engagement. If it contains a percentage score and no attempt counts, ask for the attempt counts.
ioSENTRIX is a CREST-accredited penetration testing firm, ISO/IEC 27001 certified and SOC 2 Type 2 attested, and our AI and ML penetration testing practice is built around the distinction this post keeps returning to: the difference between a control that exists and a control that held. We scope engagements against adversary objectives, state reproduction rates with attempt counts, and name what was out of scope. We assure the stack you have chosen; we do not sell a competing platform.
Independent adversarial testing is what produces this kind of evidence — whoever performs it. If you want to talk through what would be worth testing first, schedule a consultation.